
2026 Best Mini PC for AI Local LLMs & Image Generation
An AI Mini PC is a compact computer designed to run artificial intelligence workloads locally, including large language models, image generation tools, and automation systems. It integrates a CPU, GPU, and NPU to deliver efficient offline AI computing with low power consumption. The best Mini PC for AI in 2026 combines 64GB+ RAM, modern AMD Ryzen AI or Intel Core Ultra processors, and energy-efficient designs.
Key Takeaways:
- AI Mini PCs can run local LLMs like Llama 3 and Mistral without cloud subscriptions
- 128GB RAM is now available for serious AI workloads
- The NPU (Neural Processing Unit) handles light, always-on Windows AI tasks efficiently; local LLMs run mainly on the GPU/iGPU and unified memory
- Power consumption ranges from 15W idle to 85W under load, far lower than traditional desktops
- ACEMAGIC offers purpose-built AI Mini PCs starting with the M1A PRO+ AI MAX+395

Why It Matters in 2026
In 2026, AI Mini PCs are increasingly replacing cloud-based AI tools for many users because they reduce subscription costs, improve privacy, and allow faster response times without internet dependency. They are widely used for running LLMs like Llama 3, generating AI images, and building personal AI servers.
Before choosing an AI Mini PC, understanding the differences between Mac and Windows platforms can help determine the right hardware ecosystem for your workflow.
High-performance platforms such as the Ryzen AI Max 395 mini PC have accelerated this shift by enabling large-model inference directly on consumer hardware.
Core hardware components include:
- Modern CPU (Intel Core Ultra or AMD Ryzen AI series)
- Integrated NPU (Neural Processing Unit) for AI acceleration
- High-capacity RAM (16GB to 128GB)
- Fast NVMe SSD storage
- Optional dedicated GPU for heavy AI tasks
According to AMD’s official specifications, the Ryzen AI Max+ 395 features an integrated NPU delivering up to 50 TOPS of AI compute. In comparison, the total platform AI performance (CPU + GPU + NPU) reaches up to 126 TOPS.
What Real Users Are Saying
AI Mini PC discussions across Reddit communities such as r/LocalLLaMA, r/MiniPCs, and r/homelab reveal consistent real-world usage patterns.
RAM Is the Most Important Factor in Real AI Workloads
Users repeatedly emphasize that memory matters more than CPU or brand. Many users report that upgrading RAM provides more noticeable improvement than upgrading CPU.
Typical real usage breakdown:
- 16GB: Small models (7B parameters)
- 32GB: Stable image generation and light AI workloads
- 64GB: Larger quantized models (for example 70B-class) may fit depending on quantization, context length, and free memory
- 128GB: Professional AI development setups
Shift from Cloud AI to Local AI Systems
Users are increasingly moving away from cloud APIs due to:
- Subscription costs
- Privacy concerns
- Offline usage needs
Common local tools include Ollama and LM Studio for running models directly on Mini PCs.
Ryzen AI 395 Is the Sweet Spot
The AMD Ryzen AI MAX+395 processor is frequently recommended for local AI inference. Users praise its 128GB unified memory and Radeon 8060S integrated graphics, which carry most local LLM work, calling it one of the best options for local LLM inference. Its NPU handles light, always-on Windows AI tasks rather than the main model workload.
This is why the Ryzen AI Max 395 mini PC has become a reference point for high-end AI Mini PC builds.

What Actually Determines AI Performance
AI Mini PC performance depends on three key components:
CPU (General Processing)
Handles system tasks and responsiveness but is not the main AI bottleneck. Modern AI Mini PCs use Intel Core Ultra or AMD Ryzen AI processors with 8-16 cores.
GPU (Parallel AI Workload)
Critical for image generation, video rendering, and Stable Diffusion performance. Some AI Mini PCs include dedicated GPUs for users who need maximum AI performance.
NPU (AI Inference Engine)
Optimized for light, always-on Windows AI tasks such as background blur, noise suppression, and other on-device features, at low power. Local LLMs in tools like Ollama and llama.cpp run mainly on the GPU/iGPU and unified memory, not on the NPU.
Modern Intel and AMD platforms integrate NPUs designed for efficient background AI tasks.
Choosing the right processor is also important for AI Mini PC performance. Learn more about the differences between AMD Ryzen 5 and Intel i5 processors.
Real-World Performance: Benchmarks
Understanding how AI Mini PCs perform in real-world tasks helps you choose the right model.
LLM Inference Speed
| Model | ACEMAGIC M1A PRO+ (128GB) | ACEMAGIC F5A (32GB) | ACEMAGIC K1 (16GB) |
|---|---|---|---|
| Llama 3 8B | High performance class (approx. 70–120 tokens/s) | Mid-high class (approx. 25–45 tokens/s) | Entry class (approx. 10–20 tokens/s) |
| Llama 3 70B | Possible with 4-bit quantization (slow, ~10–18 tokens/s) | Not practical (memory limit 32GB tight) | Not enough RAM |
| Mistral 7B | High performance (approx. 90–150 tokens/s) | Mid class (approx. 30–60 tokens/s) | Low-mid class (approx. 15–30 tokens/s) |
| Phi-3 Mini | Very high performance (approx. 140–220 tokens/s) | High performance (approx. 50–90 tokens/s) | Mid performance (approx. 25–50 tokens/s) |
Image Generation Speed (Stable Diffusion)
| Task | ACEMAGIC F5A | ACEMAGIC M1A PRO+ | ACEMAGIC K1 |
|---|---|---|---|
| 512x512 (1 image) | ~4–8 sec (RDNA 3.5 iGPU class) | ~2–5 sec (high-end iGPU class, Radeon 8060S) | ~8–15 sec (Vega 7 limit) |
| 1024x1024 (1 image) | ~10–20 sec | ~5–12 sec | ~15–30 sec |
| Batch (10 images) | ~40–90 sec | ~20–50 sec | ~80–180 sec |
Power Consumption
| System | Idle | Load | Estimated 24/7 Cost |
|---|---|---|---|
| ACEMAGIC M1A PRO+ | ~15W | ~65W | ~USD 12/month |
| ACEMAGIC F5A | ~18W | ~85W | ~USD 16/month |
| Traditional Desktop | ~80W | ~350W | ~USD 65/month |
Sources: AMD Ryzen AI Max+ 395 specifications, AMD Ryzen AI 9 HX 470 specifications, AMD Ryzen 5 7430U specifications
Note: Performance values are estimated based on CPU/GPU/NPU specifications and typical AI inference scaling behavior. Actual results may vary depending on model size, quantization level (FP16 / INT8 / 4-bit), runtime (llama.cpp / ONNX / Vulkan / Metal), thermal constraints, and system configuration.
Which AI Mini PC Should You Buy in Late 2026?
Skip chasing TOPS first. Match the job to memory capacity and software path, then pick a chassis you can actually buy.
| Your job | ACEMAGIC pick | Why this lane |
|---|---|---|
| Light AI agents and automation (OpenClaw-style workflows, small coding models) | F2A (Ryzen AI 9 HX 470, 32GB) | Entry path for OpenClaw pre-install and small GGUF agents. 32GB system memory shared with integrated graphics suits lighter models and short context—not a 70B comfort zone. |
| Daily local LLM plus light image work | M1A PRO+ (Ryzen AI Max+ 395, 128GB) | Larger unified memory for everyday chat/coding with KV headroom. Radeon 8060S class integrated, not discrete CUDA. |
| Bigger models, longer context, more concurrent local work | F9A PRO (Ryzen AI Max+ PRO 495, 192GB) | A higher-capacity workstation option for workloads that exceed the practical memory headroom of a 128GB system. Actual model compatibility depends on quantization, context length, and inference software. |
| CUDA apps, discrete-GPU workflows, gaming on the side | M1A PRO (Core i9-13900HK + RTX 5060) | Discrete GeForce RTX 5060 for CUDA-heavy tools and gaming on the side. |
Muse Glimmer: A Practical Local AI Example
If you want a concrete “can I run this locally?” check from Meta’s new catalog, use Muse Glimmer—not the API-hosted Muse Spark/Wonder line. It’s Meta’s ~30B open-weight multimodal model meant for self-hosting (llama.cpp and similar). See the Meta Models overview for how hosted vs open-weight lines are split.
A practical starting point is Meta’s published Q4_K_M GGUF: about 16.8GB for the text weights, plus roughly 1.4GB if you also load the vision projector. File sizes are listed on the Muse Glimmer 30B GGUF page.
Based on weight size, a text-first Glimmer build is a realistic capacity fit for a 128GB Strix Halo system such as the M1A PRO+. A 32GB system such as the F2A 470 may also accommodate it with a modest context window and sufficient memory left for the OS, KV cache, runtime, and other tools. These are memory-planning estimates, not tested performance claims for either mini PC. Confirm model support in your runtime and compatibility with the selected CPU/GPU backend; treat file size as the floor, not the total runtime requirement.
Muse Spark Open is a separate, much larger open Spark release—don’t size your mini PC against it the way you’d size Glimmer.
Model Weights Are Not the Same as Runtime Memory
The model tables later in this guide talk about how much system memory you may need to run different model sizes. This section answers a different question: how big are the official weight files, and why you should not treat that number as your shopping RAM target.
A practical way to think about it:
Runtime memory ≈ model weights + KV cache + runtime overhead
The weight file is only the floor. KV cache grows with context length and concurrent sequences. Frameworks (llama.cpp, Ollama, vLLM, and similar) add overhead. So a 9 GB GGUF does not mean “buy 9 GB of RAM,” and a pack marketed around 24 GB weights is still not a full runtime measurement once context gets long.
| Official model/file | Quant/pack | Weight file size (sourced) | Why this is not your RAM shopping number |
|---|---|---|---|
| Qwen2.5-Coder-3B-Instruct · qwen2.5-coder-3b-instruct-q4_k_m.gguf | Q4_K_M GGUF | 2.10 GB | File size only. KV + OS + framework still sit on top. |
| Qwen3-4B · Qwen3-4B-Q4_K_M.gguf | Q4_K_M GGUF | 2.50 GB | Same: weight floor, not end-to-end runtime. |
| Qwen2.5-Coder-7B-Instruct · qwen2.5-coder-7b-instruct-q4_k_m.gguf | Q4_K_M GGUF | 4.68 GB | Common coding GGUF size class—still not a “needs 4.68 GB RAM” claim. |
| Qwen3-8B · Qwen3-8B-Q4_K_M.gguf | Q4_K_M GGUF | 5.03 GB | Weight file size ≠ minimum system memory. |
| Qwen3-14B · Qwen3-14B-Q4_K_M.gguf | Q4_K_M GGUF | 9.00 GB | Longer context widens the gap between file size and runtime. |
| Qwen2.5-32B-Instruct · Q4_K_M multi-shard | Q4_K_M GGUF | 19.85 GB (sum of shards) | A roughly 20GB Q4 weight pack can still leave room—or not—on 32GB or 64GB machines depending on context and free memory. That decision belongs in the requirements tables below, not in this file-size column. |
| NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB | Native IQ2 / 2-bit pack; 74B total / 9B active | Approximately 24GB packed model, as specified by NVIDIA. Repository storage size is not a measured runtime memory requirement. | NVIDIA's published deployment support does not establish equivalent compatibility or performance on AMD Radeon systems. Not Lightning. |
GGUF sizes from Hugging Face file listings. Bolt wording from the NVIDIA model card. For “how much RAM should I buy?”, use the requirements tables later in the article—not this list.


Scenario Guide: Solving Your Specific Problems
Different users face different problems. Here are real scenarios, each addressing a specific pain point, and how an AI Mini PC can solve it.
I want to play games, but I don't want a noisy, bulky desktop
Pain Point: Traditional gaming desktops are large, noisy, and power-hungry.
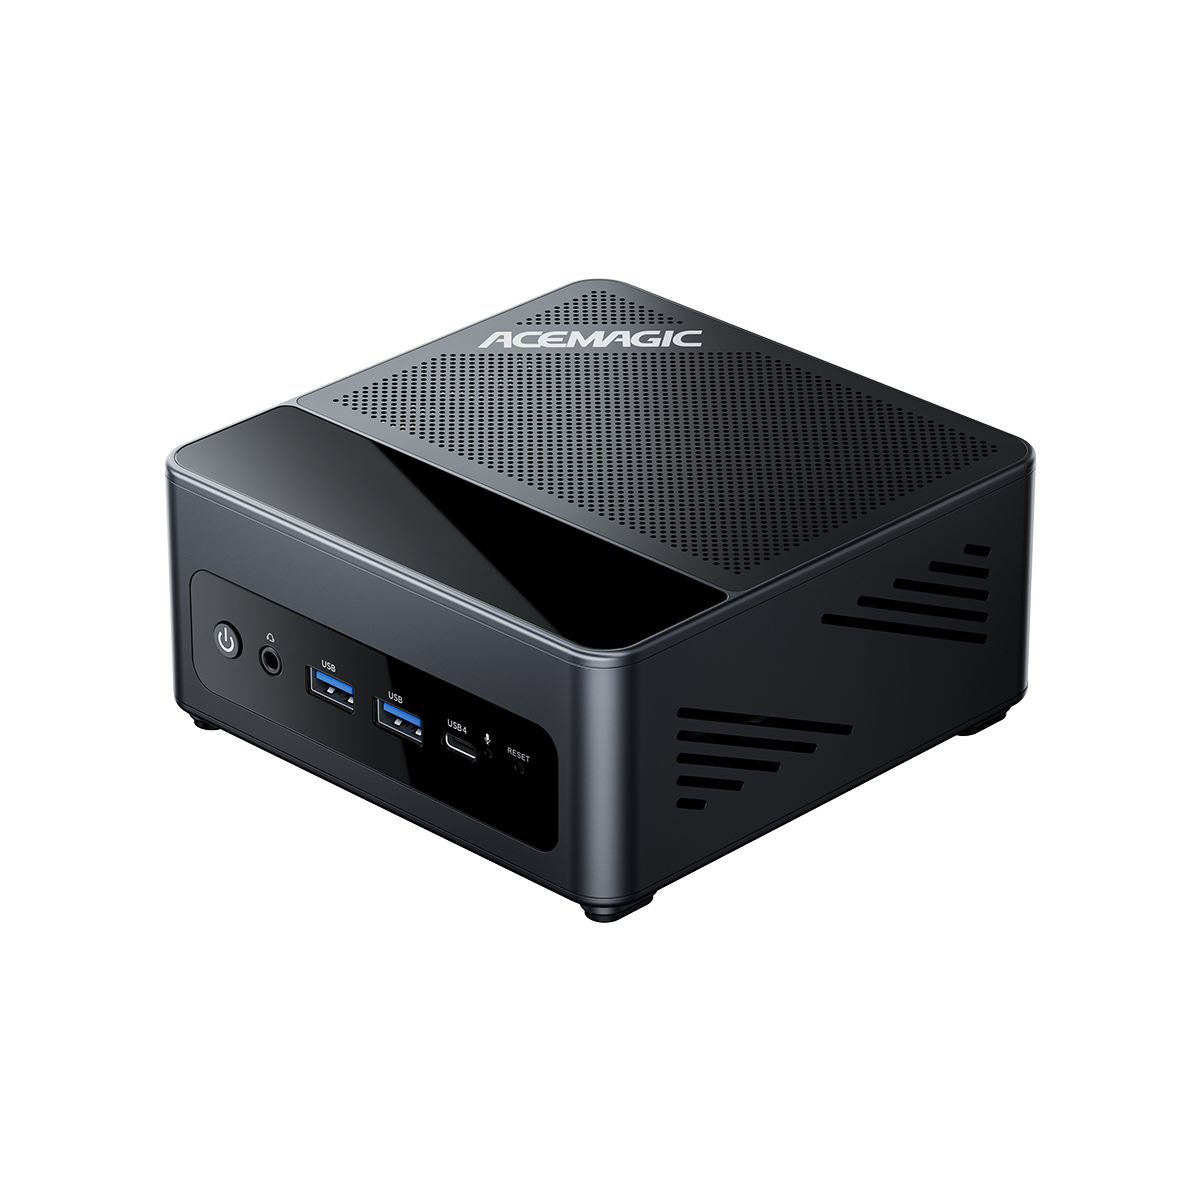
Solution: Look for the best Mini PC for AI with discrete graphics when you need faster 1080p esports. The ACEMAGIC F5A uses integrated Radeon 890M; for smoother 1080p esports use a discrete-GPU chassis such as M1A PRO RTX 5060. F5A still offers:
- Compact design (5-7 inches), doesn't take up desk space
- Integrated Radeon 890M (RDNA 3.5) for light gaming; add an external GPU dock via OCuLink if you need more
- Low fan noise for a quieter gaming experience
- Power consumption is 60% lower than traditional desktops
What you can play: Esports games (League of Legends, CS2, Valorant), 1080p medium-high settings AAA games

I want to use Stable Diffusion, but cloud services are too expensive
Pain Point: Midjourney, DALL-E, and other cloud services cost USD 20-60 per month. Costs add up quickly when generating lots of images. Concerned about the privacy of images uploaded to the cloud.
Solution: Choose the best Mini PC for AI with a dedicated GPU and sufficient RAM:
- Dedicated GPU for fast image generation
- At least 32GB RAM (64GB recommended for large models)
- One-time purchase, no monthly fees
- Runs locally, images never leave your computer
Cost comparison:
- Cloud service(Midjourney): USD 30/month x 12 months = USD 360/year
- AI Mini PC (one-time): USD 1,499-3,399, lasts 3+ years
I want to use ChatGPT, but I don't want to pay USD 20/month
Pain Point: ChatGPT Plus costs USD 20/month, USD 240/year. Company secrets and personal data uploaded to the cloud. Can't use without an internet connection.
Solution: Choose an AI Mini PC with high RAM capacity and a capable GPU/iGPU:
- At least 64GB RAM when you plan larger quantized models; 128GB gives more headroom depending on quantization, context length, and free memory
- Enough free memory for the quantized model plus KV cache; CPU/GPU backend for GGUF stacks
- One-time purchase, no monthly fees
- Runs locally, data never leaves your computer
Cost comparison:
- ChatGPT Plus: USD 20/month x 12 months = USD 240/year
- AI Mini PC (one-time): USD 1,159-6,499, lasts 3+ years
Available memory determines which model configurations can run without excessive offloading. Memory bandwidth, compute capability, inference backend, and workload characteristics influence how quickly tokens are processed and generated. A larger unified-memory system can open more model configurations than a smaller-RAM box with a discrete GPU, but that is not a claim that GPU never matters for speed.
I edit 4K video, but rendering is too slow
Pain Point: 4K video rendering takes too long. Traditional workstations are large and expensive (USD 3,000+).
Solution: Choose an AI Mini PC with a dedicated GPU:
- Dedicated GPU accelerates video rendering
- At least 32GB RAM (64GB recommended for 4K)
- Compact design fits in a backpack
- 50% cheaper than traditional workstations
I want to run local AI services 24/7, but worried about electricity
Pain Point: Traditional servers consume 350W+, costing USD 65+/month.
Solution: Choose an AI Mini PC with low power consumption and high RAM:
- Low idle power consumption (~15W)
- At least 64GB RAM (128GB recommended for multiple services)
- Stable and reliable for long-term operation
24/7 operating cost comparison:
- Traditional server: High power (350W+), monthly electricity USD 65+
- AI Mini PC: Low power (15-65W), monthly electricity USD 12
- Annual electricity savings: ~USD 600
How People Actually Use Them
Local AI Developer Setup
Developers run LLMs locally to avoid API costs and latency. Common setups include Ollama or LM Studio running quantized 70B models.
AI Content Creation Workflow
Creators use GPU-based systems for Stable Diffusion, ComfyUI pipelines, and batch image generation.
Home AI Server
Users replace cloud AI subscriptions with local Mini PCs running continuously for chatbot hosting and automation.
Office Productivity + AI Assistant
Light users rely on Mini PCs for writing, translation, and coding assistance without heavy hardware requirements.
How to Choose the Best Mini PC for AI
Step 1: Identify Your Workload
| Workload Type | Key Requirement |
|---|---|
| Text AI (LLM inference) | High available memory; CPU and/or GPU backend (NPU is not the main GGUF path) |
| Image AI (Stable Diffusion) | GPU required |
| Video editing | GPU required |
| Office + light AI | Compact, quiet, affordable |
| 24/7 AI server | Low power, high RAM, stable |
Step 2: Choose RAM Based on Model Size
| RAM | What You Can Do |
|---|---|
| 16GB | Basic AI tasks, small models (7B parameters) |
| 32GB | Most AI workloads including image generation |
| 64GB | Larger quantized models (for example 70B-class), depending on quantization, context length, and free memory |
| 128GB | Professional AI development, multi-model setups |
Step 3: Decide GPU Requirement
GPU acceleration helps image generation and video processing. For text LLMs, local stacks like Ollama and llama.cpp usually run on CPU and/or GPU. An NPU helps certain Windows on-device features; it is not the main path for most GGUF chat. Available memory determines which model configurations can run without excessive offloading. Memory bandwidth, compute capability, inference backend, and workload characteristics influence how quickly tokens are processed and generated.
Step 4: Consider Power Usage
Lower power systems are better for 24/7 operation scenarios. Typical AI Mini PCs consume 15-85W, compared to 80-350W for traditional desktops.
AI Mini PC vs Traditional Desktop
| Feature | AI Mini PC | Traditional Desktop |
|---|---|---|
| Size | Compact (5-7 inches) | Large tower |
| AI Acceleration | CPU + GPU + NPU | GPU-dependent |
| Power Usage | 15-85W | 80-350W |
| Noise | Low | Medium-High |
| Upgradeability | Limited | High |
| Best Use Case | AI workloads + office | Gaming + rendering |
AI Mini PCs prioritize efficiency and continuous AI workloads, while traditional desktops prioritize raw performance.
Who Should Use the Best Mini PC for AI?
Ideal users include:
- Developers running local AI models for coding assistance
- Content creators using AI tools for video and image editing
- Remote workers who need a compact, quiet workstation
- Students and researchers working with machine learning
- Users building personal AI servers for home use
AI Mini PCs may not be ideal for:
- Hardcore AAA gamers who need maximum frame rates
- 3D animation professionals requiring high-end GPU rendering
- Users who need frequent hardware upgrades
Is an AI Mini PC Worth It in 2026?
An AI Mini PC is worth buying if you want:
- Local AI execution without cloud subscription costs
- A compact workstation that fits on any desk
- Low power consumption for 24/7 operation
- Balanced performance for productivity and AI tasks
Consider alternatives if you need:
- High-end GPU rendering for professional 3D work
- Maximum upgrade flexibility with standard PC components
- AAA gaming at 4K ultra settings
What Best Mini PC for AI Models?
For running local AI models, an AI Mini PC provides excellent value. You need at least 32GB RAM (64GB recommended), a capable GPU or iGPU with enough unified memory, and fast NVMe SSD storage. An NPU is useful for light, always-on Windows AI tasks, but it is not the main LLM accelerator.
The ACEMAGIC M1A PRO+ AI MAX+395 meets these requirements with up to 128GB unified memory and Radeon 8060S integrated graphics for local LLMs; its NPU covers light, always-on Windows AI tasks.
F5A pairs Ryzen AI 9 HX 470 with integrated Radeon 890M; OCuLink is for an external GPU dock, not an onboard dedicated GPU. For discrete-GPU performance, choose a chassis such as ACEMAGIC M1A PRO with RTX 5060.
Out-of-the-Box AI Computer: Ready to Use
One significant advantage of ACEMAGIC AI Mini PCs is that they work out of the box. Unlike custom-built systems that require assembly and configuration, ACEMAGIC mini PCs come pre-configured with optimized BIOS settings, compatible RAM and storage, and a ready-to-use Windows installation.
Best Local AI Model for CPU: What to Run
These tables estimate system-memory headroom for different model scales. They are not GGUF file sizes—see “Model Weights Are Not the Same as Runtime Memory” for official weight-file sizes.
| Model | RAM Required | Best For |
|---|---|---|
| Llama 3 (8B) | 16GB | General chat and text generation |
| Mistral 7B | 16GB | Fast inference and coding tasks |
| Llama 3 (70B) | 64GB+ (depends on quantization, context length, and free memory) | Advanced reasoning and analysis |
| Phi-3 Mini | 8GB | Lightweight AI tasks |
| Stable Diffusion | 16GB+ | Image generation |
AI Model Requirements Reference
These tables estimate system-memory headroom for different model scales. They are not GGUF file sizes—see “Model Weights Are Not the Same as Runtime Memory” for official weight-file sizes.
| Model | Minimum RAM | Recommended Use |
|---|---|---|
| Llama 3 8B | 16GB | Chat and basic AI tasks |
| Mistral 7B | 16GB | Coding assistant |
| Llama 3 70B | 64GB+ (depends on quantization, context length, and free memory) | Advanced reasoning |
| Phi-3 Mini | 8GB | Lightweight tasks |
| Stable Diffusion | 16-32GB + GPU | Image generation |
Future Trends of AI Mini PCs
- Increasing adoption of NPU-based AI computing
- 64GB–128GB RAM becoming mainstream
- Growth of local AI replacing cloud AI usage
- AI-native operating systems emerging
- Expansion of edge AI computing devices
Frequently Asked Questions
What is an AI Mini PC used for?
Do AI Mini PCs need a GPU?
Image generation and video processing usually benefit from GPU acceleration. Text LLMs can run on CPU and/or GPU backends (Ollama, llama.cpp, and similar); an NPU helps certain Windows on-device features but is not the main path for most GGUF chat.
How much RAM do I need for AI workloads?
At least 16GB is a common floor for small models. Larger models need more available memory; 64GB or more is a frequent planning range, but exact fit depends on quantization, context length, and free memory.
Can AI Mini PCs run Stable Diffusion?
Yes, but GPU-equipped models provide significantly better performance for image generation.
Can AI Mini PCs run 70B models locally?
Often yes on 64GB–128GB systems, but only when quantization, context length, and free memory leave enough headroom—file size alone is not the full runtime requirement.
Are AI Mini PCs good for 24/7 usage?
Yes, they are designed for low power consumption and continuous operation.
What is the best Mini PC for AI in 2026?
The best AI Mini PC depends on your needs. For local LLM inference, choose a model with 128GB unified memory and strong integrated graphics (like ACEMAGIC M1A PRO+), because local LLMs run mainly on the GPU/iGPU and unified memory; the NPU covers light, always-on Windows AI tasks. For gaming/video editing that needs discrete CUDA-class graphics, choose a model with a dedicated GPU (like ACEMAGIC M1A PRO with RTX 5060).
How much does an AI Mini PC cost?
ACEMAGIC AI Mini PCs in this guide range from USD 1,159 to USD 6,499. The F2A with Ryzen AI 9 HX 470 and 32GB is USD 1,159, the M1A PRO with RTX 5060 is USD 1,499, the M1A PRO+ with Ryzen AI Max+ 395 and 128GB is USD 3,399, and the F9A PRO workstation with Ryzen AI Max+ PRO 495 and 192GB is USD 6,499. Basic office mini PCs for light AI use cost less.
Final Notes
The Best Mini PC for AI represents a shift toward local-first computing. As hardware continues to improve, systems like the ryzen ai max 395 mini pc are becoming the foundation for personal AI infrastructure, replacing many cloud-based workflows.
For users looking for ready-to-use solutions with strong performance and flexible configurations, ACEMAGIC offers a range of AI Mini PCs designed for local LLM workloads, content creation, and everyday productivity.





1 comment
hello